Datasource to monitor Windows Services/Processes automatically?
Hello,
We recently cloned 2 Logic Monitor out of the box datasources (name -> WinService- & WinProcessStats-) in order to enable the 'Active Discovery' feature on those.
We did this because we've the need to discover services/processes automatically, since we don't have an 'exact list' of which services/processes we should monitor (due to the amount of clients [+100] & the different services/solutions across them)
After enabling this it works fine & does what we expect (discovers all the services/processes running in each box), we further added some filters in the active discovery for the services in order to exclude common 'noisy' services & grab only the ones set to automatically start with the system.
Our problem arrives when these 2 specific datasource start to impact the collector performance (due to the huge amount of wmi.queries), it starts to reflect on a huge consumption of CPU (putting that on almost 100% usage all the time) & that further leads to the decrease of the collector performance & data collection (resulting in request timeouts & full WMI queues).
We also thought on creating 2 datasources (services/processes) for each client (with filters to grab critical/wanted processes/services for the client in question) but that's a nightmare (specially when you've clients installing applications without any notice & expecting us to automatically grab & monitor those).
Example of 1 of our scenarios (1 of our clients):
- Collector is a Windows VM (VMWare) & has 8GB of RAM with 4 allocated virtual processors (host processor is a Intel Xeon E5-2698 v3 @ 2.30Ghz)
- Currently, it monitors 78 Windows servers (not including the collector) & those 2 datasource are creating 12 700 instances (4513 - services | 8187 - processes) - examples below
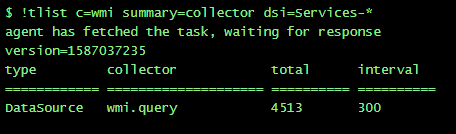 This results in approx. 15 requests per second
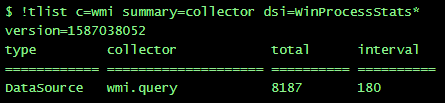 This results in approx. 45 requests per second
According to the collector capacity document (ref. Medium Collector) we are below the limits (for WMI), however, those 2 datasource are contributing A LOT to make the queues full.
We're finding errors in a regular basis - example below

To sum this up, we were seeking for another 'way' of doing the same thing without consuming so much resources on the collector end (due to the amount of simultaneous WMI queries). Not sure if that's possible though.
Did anyone had this need in the past & was able to come up with a different solution (not so resource exhaustive)?
We're struggling here mainly because we come from a non-agent less solution (which didn't faced this problem due to the individual agent distributed load - per device).
Appreciate the help in advance!
Thanks,

Herin
·6 years agoPlease ignore my above post ... dont know what i was thinking.?
Herin
·6 years agoThanks Mike , Vitor & Stuart for this datasource. Much Appreciated
Notice there is a ProcessID normal datapoint which doesnt have any threshold value set. We can alert if there is no data available which can mean the process is not running but if we want to setup alert trigger interval what would be the alert threshold?
Can we configure something like below as a complex datapoint?
LM User
·6 years agoThis is exactly what I attempted to do, but I took it a step further. The WMI collector polls the string contained in status/state and checks for presence of one good value. Since this version is groovy, we can enumerate like this:
I took all the possible values and tried to sort them into ascending order of problem so that 0 is the optimum state and the higher the number, the higher the criticality of the problem. If you have suggestions on a better, I'm completely open to reordering this.
Vitor_Santos
OP6 years agoOh I see.
Well, I guess despite that, diving by the number of cores will reflect the process usage on the whole CPU anyways, right?
Even if it's not split evenly, that calculation will reflect the actual process use over the CPU (in a whole). Maybe I'm confusing.
Mike Moniz
·6 years agoAnother suggestion for the services check, although this does deviate from the existing WinServices- check is instead of doing 0=Not OK and 1=OK, is to set 0=OK and 1=Not OK. Several other LM Datasources generally work this way in that the larger the number the more urgent the problem so you can do thresholds like > 0 1 2. In this case it that doesn't matter since it's binary option, but it also helps with widgets like table color bars where < does not work very well or gauge widgets and others that also seem to assume this.
LM User
·6 years agoYes, that needs to happen. Otherwise, this metric is very much like CPULoad in Linux boxes, where 100% = one fully loaded core. The thing is that you can't just divide by the number of cores, because you don't know for sure that the threads are split evenly across cores.
Vitor_Santos
OP6 years agoThanks a lot for sharing!
I've applied that to my datasource as well.
By checking the values against a process that's currently consuming 30-36% of the CPU, it's returning values like '143.5667' for that ProcessCPUPercent.
I guess we need to divide that number by the number of CPU Cores for the server in question.
In my case the box I'm testing that has 4 CPU Cores, which results in a value of 35.89%.
It seems to reflect the actual usage of the process (shown in Task Manager) ?
LM User
·6 years agoSo, this is what I ended up with (publishing to GitHub after a bit more data is gathered). Notice PercentProcessorTime is a counter and the formula on the complex dp.
LM User
·6 years agoDuh, i need to multiply by 100 to convert it to percent.
LM User
·6 years agoThis is exactly what changing the datapoint to type counter does. It takes the delta between the current polled value and the previously polled value and divides by the time between the two polls.
The results i'm getting are pretty low, like too small by a factor of 10 or 100.
Vitor_Santos
OP6 years agoYeah I've also been googling about this & found a bunch of threads, however, I got kinda confuse. Did some tests & the results were definitely not accurate.
Hoping @Stuart Weenig to make it work!
It would definitely be useful!
Mike Moniz
·6 years agoI've had problems attempting to do that in the past outside of LM but haven't really resolved it (kinda gave up at the time). I think you need to query the value twice over a set period and also take into account the number of logical cores in the system has. But even doing that I intermittently was getting weird results like 72025954.98% cpu. You'll see some various discussions on replicating task manager per-process cpu % via wmi on google.
It would be great if there was a good solution to this though.
Vitor_Santos
OP6 years agoThat's awesome!
Can you share it once you have it working?
LM User
·6 years agoIt's funny, but my lab windows box is unlicensed, so i have about an hour to test stuff until it shuts off. Not a big deal to turn it back on, but it's making things slower. The first thing I did was convert PercentProcessorTime to a counter. That changed the values such that I'm now getting the delta between the current value and the previous poll's value divided by the time between them. So, theoretically, the resulting number should be pretty close, just needs to be adjusted to convert 100s of ns/s to unitless (%). Should mean just dividing the PercentProcessorTime (as a counter) by 10. Got that in now and i'm going to let it bake to see if the results make sense.
Vitor_Santos
OP6 years agoHey Stuart!
I noticed that this morning & was going to reference that in a bit. Glad you noticed it, because I was going to post in the communities asking for some help.
We were seeking in having the process actual CPU usage (like we see on TaskManager for example - for the whole CPU).
Would be nice if you actually figure out what calculation is required to do that.
LM User
·6 years agoI'm thinking some of the datapoints on the process DS needs to be adjusted. The PercentProcessorTime, for example, is not an actual percent. It's measured in 100s of nanoseconds since the process started. Which means it's more like a counter than a gauge. I'm going to do some testing.
LM User
·6 years agoProcess monitoring groovified: https://github.com/sweenig/lmcommunity/tree/master/ProcessMonitoring/Win_Process_Stats_Groovy
Looking into adding that option @Mike Moniz.
Mike Moniz
·6 years agoAs a thought, if you add a new datapoint "ProcessId" which outputs the process id of the Windows Service (which is a number), you can then use the delta threshold to cause an alert if the service restarts between checks. Just as an option if it's ever needed at the instance level.
LM User
·6 years agoNo worries at all. I thought Groovy was a made up language when I got my LM interview exam. ?
I've groovified your services DS. It's here. I'll work on the process one tomorrow. You should be able to see the ad.groovy and collect.groovy scripts right there in the repo, so you can take a look at how I simplified it. Unfortunately for groovy, I can make condensed, simpler code that is harder to read (python, for example, won't really let you make something so condensed that it's unreadable).
Vitor_Santos
OP6 years agoahah that's nice!
I'm not an experienced programmer, well, I'm not even a programmer ? excuse me for any noob stuff on the code.
LM User
·6 years agoThis one is enough. The Exchange area of the community is for asking questions about stuff already in the exchange. Give it some time though. Once the new exchange is rolled out, you'll be able to publish it yourself and maintain it on our exchange with version control and everything. I'm cleaning it up a bit before i put it into my repo. Once i do, i'll post here and you can test it out to make sure it works the same. There is some grooviness I can add to your code to make it simpler.
Vitor_Santos
OP6 years agoNot at all, feel free to use them.
I was thinking on submitting a thread in LM Exchange containing those 2 datasources but I didn't wanted to create repeated threads (like I did a couple of days ago ?).
Let me know if we should submit a post within LM Exchange containing those 2 datasources for future record or, if this one is enough for the sharing purpose.
Regards,
LM User
·6 years agoWould you mind if I merged these into my repo?
Vitor_Santos
OP6 years agoPlease find both datasource within https://github.com/vitor7santos/LogicMonitor.git
They're named:
- Services.xml
- WinProcessStats.xml
Regards,
Vitor_Santos
OP6 years agoThanks a lot for the feedback & ideas @Mike Moniz & @Stuart Weenig!
We really enjoyed Mike suggestion of doing a script to actually poll the data in bulk - per device (instead of 1 query per service/process instance).
After reading some documentation & understanding how to use WMI on groovy (with help of some OutOfBox datasources) we ended up by rebuilding those 2 datasources (services & processes) using groovy (making use of the WMI class).
They're collecting exactly the same metrics as the out of the box ones & after 2/3 hours in production those really reduced the collector CPU/Memory usage - used 1 of our clients as a pilot
Previously the usage was constantly at >98%, now it's monitoring the same amount of services/processes & using 60-70% of CPU.
It increased the groovy instances exponentially - examples below
However, this doesn't seem to affect the collector resources usage that much.
We're also no longer seeing the WMI timeouts on the WMI instance runs. We guess this is really making a difference.
I know it's too soon to say this solved it, but by judging how the resource usage looks, this seems to make a big difference.
Also, the list of services changes, that's why we ended up using a property.
I'll share both datasources with you guys in a few minutes (I'll just attach the .XML file(s) to this thread) in case this is useful for anyone.
Regards,
LM User
·6 years agoYes, using batchscript will definitely improve your performance since it should do one fetch per device, instead of one fetch per service.
So, your discovery filter is set to include only services where the start mode is "Automatic". And you've got another discovery filter that excludes the services that no one cares about. If that list is the same and never changes, no need to put it in a property, it's just over-complicating things.
So, it's working? Did you make a version for the process monitoring?
Daniel Blanco
·6 years ago@Stuart Weenig so just some background what we (Vitor and I work at same MSP) are trying to replicate in LogicMonitor is what UIM's ntservices & processes probe can do. We are migrating to LM and looking to replicate our existing UIM functionality in LM. The way we configured the ntservices probe is once deployed with the custom package is to auto monitor all services set to Automatic minus all the known excluded services that no one cares about. The same goes for the processes probe. We monitor all processes on a box and alert on any individual process that spikes to over say 95% cpu for more than 15 min. So both of these (ntservices & processes) probes ran locally on each resource. But now using this batch script method seems to be helping out on the overall resource usage on each collector.
Mike Moniz
·6 years agoHa, I just realized I have used it before to create PropertySources based on https://communities.logicmonitor.com/topic/1137-use-ilps-for-applies-to/. How quickly I forget :P
Mike Moniz
·6 years ago(Sorry for semi-hijacking the thread)
Interesting and thanks! Do you have documentation on the WMI class? For example how would you pass in wmi.user and wmi.pass, which I would expect would be needed under linux or if you need to use other creds on a windows box.
LM User
·6 years agoYep: https://github.com/sweenig/monitoring-recipes/blob/master/DataSources/Groovy/WMI/WMI_Query.groovy
I'm trying to find a definitive answer, but I think the restriction is that PowerShell based datasources can only run on Windows collectors. The product team built a WMI class for groovy that's been included in the collector for several versions now. So, WMI in groovy on linux, yes. WMI in groovy on Windows, yes. WMI in powershell on linux, no (because linux can't interpret the powershell scripts). Don't quote me on this one, still looking for definitive proof.
Mike Moniz
·6 years agoCan you do WMI using groovy? I looked around before but didn't find an example. I try to use groovy when I can, although WMI is only supported on Windows collectors anyway.
LM User
·6 years agoOoo, that's a great point. Yes, the groovy based WMI query could do a single call and grab all the data. You'd have to parse through it and print each bit out, but that's easily doable with a for loop.
And keeping discovery using the WMI method is an excellent option.
Mike Moniz
·6 years agoFrom my understanding, the native WMI-based checks will make a new WMI call for each instance, so 1 WMI call for each windows service and process, hence why you see 12k of them. There are a lot of types of checks that work that way, but there is one option that will let you make one WMI call per device (if you can get all the data in one call) and extract in bulk for all instances at once: BATCHSCRIPT. I'm not sure if it would completely help in your situation, but if you switch from native WMI to using something like a PowerShell or Groovy BatchScript, you can send one WMI query to the server and get data for all services/processes at once. Scripts do cause more load on the collector than most native checks, but 150 script instances (75*2) are likely less load then 12k WMI instances.. Actually I think the collector does WMI queries via powershell anyway, not 100% sure about that, so even less of a concern.
You can still keep the old WMI AD method and just move Collector Attributes to use batchscript.
LM User
·6 years agoSeems like what it's coming down to is that you are trying to monitor more stuff than the current collector resources can handle. Only two options really: reduce collection (stricter filters) or increase collector size. You're already excluding manual and disabled services, right?
Vitor_Santos
OP6 years agoHello @Stuart Weenig,
If I understood it properly, I think we did that already with a custom property to actually filter 'noisy' services using a regex expression (on a group/device level). That helps to create exceptions indeed.
However, that leaves us with the same issue still. Due to the reasons I mentioned above.
LM User
·6 years agoAlright documentation on that DS has been updated in the repo. Take a look and see if it helps.
LM User
·6 years agoTake a look at these two datasources: https://github.com/sweenig/lmcommunity/tree/master/ProcessMonitoring. I just realized i haven't done any documentation on that part of the repo, so give me a few minutes and i'll commit some instructions.
It doesn't change how many resources are used to monitor a process, but it does do what i think you were referring to in the nightmare scenario above. They let you specify an include and an exclude filter as properties on the device level or on the group level. So, you can just provide a regex expression to dictate what you want to include and what you want to exclude in active discovery.